Methodology
How this is built
EntryData is a modeling and interpretation layer on top of public Call of Duty League data, not a raw-stats mirror. Every number on this site is computed by a reproducible pipeline; nothing is hand-typed.
Data sources
Player photos on cards and profile pages come from PandaScore first, overlaid with Liquipedia’s own infobox photo for the current roster whenever Liquipedia has one — PandaScore’s photos are frequently a stale, team-branded shot from whenever they last touched a player’s record, and Liquipedia’s community-maintained one is generally more current. Not every player has a photo from either source; the card falls back to a generated initials avatar rather than showing nothing.
What we correct for
Mode heterogeneity. Hardpoint, Search & Destroy, and Overload produce structurally different stat lines — Hardpoint yields 25–35 kills per map with heavy objective time, S&D produces around five kills with first blood carrying outsized value, and Overload rewards attacking K/D and zone captures. Every regression here includes mode as a control or fixed effect rather than pooling raw stats across modes; see the Analysis section for worked examples of what pooling them would get wrong.
Decider-map selection bias. A series’ fifth map isn’t chosen at random — it’s shaped by the losing side of map four’s veto, which means the favorite doesn’t necessarily get a fair map on the decider. A chunk of what looks like a “clutch factor” is actually a map-selection effect.
Per-map sample-size noise. A player’s K/D shouldn’t be computed by averaging every map’s own ratio equally — a 2-death Search & Destroy map is a far noisier observation than a 20-death Hardpoint map, and left uncorrected it can meaningfully inflate a player’s season number. Every player-level K/D aggregate here (weekly trends, Best Maps, season and mode splits) sums kills and deaths across maps before dividing, rather than averaging per-map ratios.
Models
Power ratings are a chronological Elo walk over match series (not maps) with K = 24, computed in statsmodels-adjacent pure Python.
Win probability is a logistic regression — statsmodels, map_win ~ team_elo_diff + rested_days + C(mode), cluster-robust by match — combined across a best-of-5 via a forward probability walk to get a series-level number. See Predictions for the live output and the public calibration tracker scoring it against reality.
Checking that tracker against a season of results found a real, specific blind spot worth stating plainly: the per-map model itself is well calibrated (a map given a 25% chance wins about 25% of the time), but the series-level number skews overconfident on favorites — a series given under 30% recovers and wins closer to 38% of the time. The most likely cause is the forward walk’s independence assumption: it treats each map in a series as its own draw, but maps within a real series aren’t fully independent — a team having a good day tends to carry across the whole series, not just one map. That correlation gives the underdog more real chances to string together an upset than five independent coin flips would. Something to account for eventually; for now, treat a series probability under ~30% as “live,” not “settled.”
Player value is the player fixed effect from a role/opponent/map/mode-adjusted K/D regression fit with pyfixest, rescaled to a 0–100-ish index. Fit as weighted least squares, weighted by each map’s death count, for the same reason described above — a low-death map is a noisier observation of a player’s skill and shouldn’t count as heavily as a high-death one. Role is a stat-based two-category proxy (anchor/slayer, derived from within-team Hardpoint hill-time rank), not the scouted IGL/Slayer/Support/Flex taxonomy — Liquipedia doesn’t expose that field.
Mode Ratings (Hardpoint/S&D/Overload, shown on the current season’s profile tab) are the same model interacted with mode instead of just controlling for it: a separate fixed effect per player per mode, each rescaled against that mode’s own distribution rather than pooled with the other two. Player value’s regression only uses mode as a control, which absorbs mode-level baseline differences into the one pooled number but never reports them — Mode Ratings answer “which mode is actually driving this player’s number,” not just “how good are they overall.” Each mode’s rating is roughly a third of the sample size of the pooled Value, so it leans on the same shrinkage-toward-50 more heavily by construction — a real, appropriately-cautious estimate for a smaller sample, not a bug. The three numbers are not comparable to each other as raw magnitudes (50 means “average Hardpoint player,” not “average player”), only within their own column.
Teammate-adjusted value is a companion number shown on player profile pages alongside Value this season, not a replacement for it. The regression above doesn’t control for teammate quality, so part of a player’s fixed effect can reflect who they play alongside rather than pure individual skill. This adds a teammate-strength term — the mean value of a player’s own teammates on that map — resolved with fixed-point iteration, since a player’s value and their teammates’ value are mutually dependent: seed with the plain Value model, refit with a teammate term computed from the current estimate, repeat until it stops moving. It settles quickly in practice. Shown as a signed delta (e.g. “+5.1 teammate-adjusted”) next to Value; a positive delta means a player rates higher once their teammates’ strength is accounted for, a negative delta means some of their raw number reflects a strong supporting cast.
How this compares to Breaking Point
Breaking Point’s leaderboard and EntryData’s value score usually agree, and where they disagree it isn’t because one of them is reading the box score wrong. Breaking Point aggregates a player’s own raw stats — kills, deaths, damage, objective time — summed or averaged across the maps they played. EntryData’s value score is different in kind, not just in inputs: it’s a player’s own fixed effect from a regression that also conditions on role, opponent strength, map, and mode within the same match, an estimate of how much better a player performed than a like-for-like replacement would have under those conditions, not a running total of their own numbers in isolation.
That distinction only shows up when something structural is baked into the raw stats but isn’t really about individual skill. Role is the clearest example on this site: comparing players match-by-match — same map, same mode, same opponent — surfaces a real K/D gap between anchors and slayers that a pooled season average doesn’t show, because pooling lets it wash out across hundreds of different matchups. A raw leaderboard has no way to separate “this player is good” from “this role structurally runs a bit hotter or colder than that one.” EntryData’s regression can, by design, since role is one of the things it explicitly holds constant.
Neither approach is more correct in general — they’re answering different questions. Breaking Point’s leaderboard says what a player’s actual numbers were. EntryData’s value score says how much a player outperformed a replacement-level peer under the same conditions. The two agree on most players and diverge on the ones where role, schedule, or map mix meaningfully shaped their raw stats.
Roles and playstyle badges
Player pages show up to four small tags, and they’re not all built the same way — worth being explicit about which ones are measured and which are typed in by hand.
Anchor / Slayer is a stat-based two-category proxy, not the scouted IGL/Slayer/Support/Flex taxonomy (Liquipedia doesn’t expose that field on player pages, and neither does Breaking Point’s box score). Within each team, players are ranked by mean Hardpoint hill time across every map they’ve played; the top 2 get “Anchor,” the rest “Slayer.” It’s re-ranked per team, so a player can be an Anchor on one roster and a Slayer after a trade to another.
AR / SMG is the one badge that isn’t derived from any stat — there’s no weapon field anywhere in the data Breaking Point, PandaScore, or Liquipedia provide, so nothing here can measure which gun a player actually used. This tag is hand-classified from the site owner’s own knowledge of the league, the same approach the “SMG meta shift” analysis piece already used for its 20 named players, now reused as a small, growing crosswalk file rather than a one-off list. Coverage is currently partial — only a couple dozen players are classified so far — and a player who isn’t in the file yet shows no weapon badge at all rather than a guess.
Entry flags the top ~15% of qualifying players by first-blood rate in Search & Destroy (first bloods per round, not per map, since a map can have several rounds each with their own first blood). Low-sample players are floored out first — the rate only counts players at or above the field’s own 25th percentile of rounds played, so a two-map call-up on a hot streak can’t outrank a full-season starter.
Clutch flags the top ~15% of players with at least one 1v2-or-harder round win this season. This one is a raw season count, not a rate — Breaking Point’s box score records clutch wins but not clutch attempts, so there’s no attempts denominator to turn it into a percentage. It’s also a genuinely rare event league-wide (the single highest season total observed is 13), which is why a raw count is treated as the signal rather than something needing further normalization.
Both Entry and Clutch use a percentile cutoff (85th) rather than a fixed player count or hardcoded stat threshold, so the badge keeps meaning “stands out from this season’s own field” as the sample grows, instead of quietly drifting stale.
What is ED Rating?
ED Rating — the number next to the “ED” chip on every player card — is EntryData’s own player value score, the same number described under Player value in Models above. It isn’t a raw stat total: it’s a player’s fixed effect from a regression that holds role, opponent, map, and mode constant, rescaled to a roughly 0–100 index where 50 is a league-average performance. A higher number means a player outperformed a like-for-like replacement under those conditions by more than a lower-rated player did — it’s not K/D, damage, or any single box-score number by itself, and two players with the same raw stats can carry different ED Ratings if they played different roles, opponents, or maps.
Hovering (or tapping, on mobile) the rating on any card shows this same summary; this section is the full version.
Try it: from stats to rating
Move the five stats on the card and watch the rating they point to. It is a straight-line fit across the newest season’s players, so it shows how much each stat matters, not the model itself.
Player card stats
Every card shows the same five season stats: K/D (kills over deaths, summed across the season), DMG/10 (damage per 10 minutes of playtime), S&D DMG (damage per Search & Destroy round), Streak (the season’s highest killstreak) and Clutch (1v2-or-harder round wins). Two of those need a note. DMG/10 covers Hardpoint, Control and Overload only: Search & Destroy is played in rounds and Breaking Point records no playtime for it, which is why S&D has its own damage stat. And damage isn’t comparable across titles: a kill took about a third less damage in Black Ops 6 and 7 than in Modern Warfare III (the data matches 100 health against 150), so a damage number from one title shouldn’t be set against another’s. Streak is blank for Black Ops 6, a field Breaking Point barely recorded that season. Every other stat and badge on the site is explained on the Glossary, and hovering (or tapping) a label shows the short version.
Player card tiers
The player card shown on the Players page and on individual profiles has three tiers, computed once from a player’s rating and nothing else — there’s no per-player styling anywhere, so a player’s card changes tier automatically the moment their rating crosses a threshold on the next site rebuild. Each card carries its tier name on the photo, the player’s leaderboard rank (where one exists), a rating meter with tick marks at the STAR and SUPERSTAR cutoffs, and the player’s AR/SMG tag when they’ve been classified.
- SUPERSTAR (rating ≥ 85) — gold-tinted glass with a gold edge and halo, a glowing gold ED chip, the largest rating in gold and gold stat values.
- STAR (75 ≤ rating < 85) — rust-tinted glass with a rust edge, a rust ED chip and a mid-size rust rating.
- PRO (rating < 75) — plain glass with a neutral edge, no tint or halo, a muted chip and the smallest rating. The default look most cards have.
The cutoffs are fixed distances above each season’s average rather than a per-season rule: every season’s ratings are scaled to 50 + 25 × z within that season’s own player pool, so 85 is 1.4 standard deviations above average and 75 is 1.0. That keeps the top tier rare (a couple of players a season) without a separate rule for each one. They were originally set at 95 and 85, which left the current season with no SUPERSTARs at all and all but two players in the same tier.
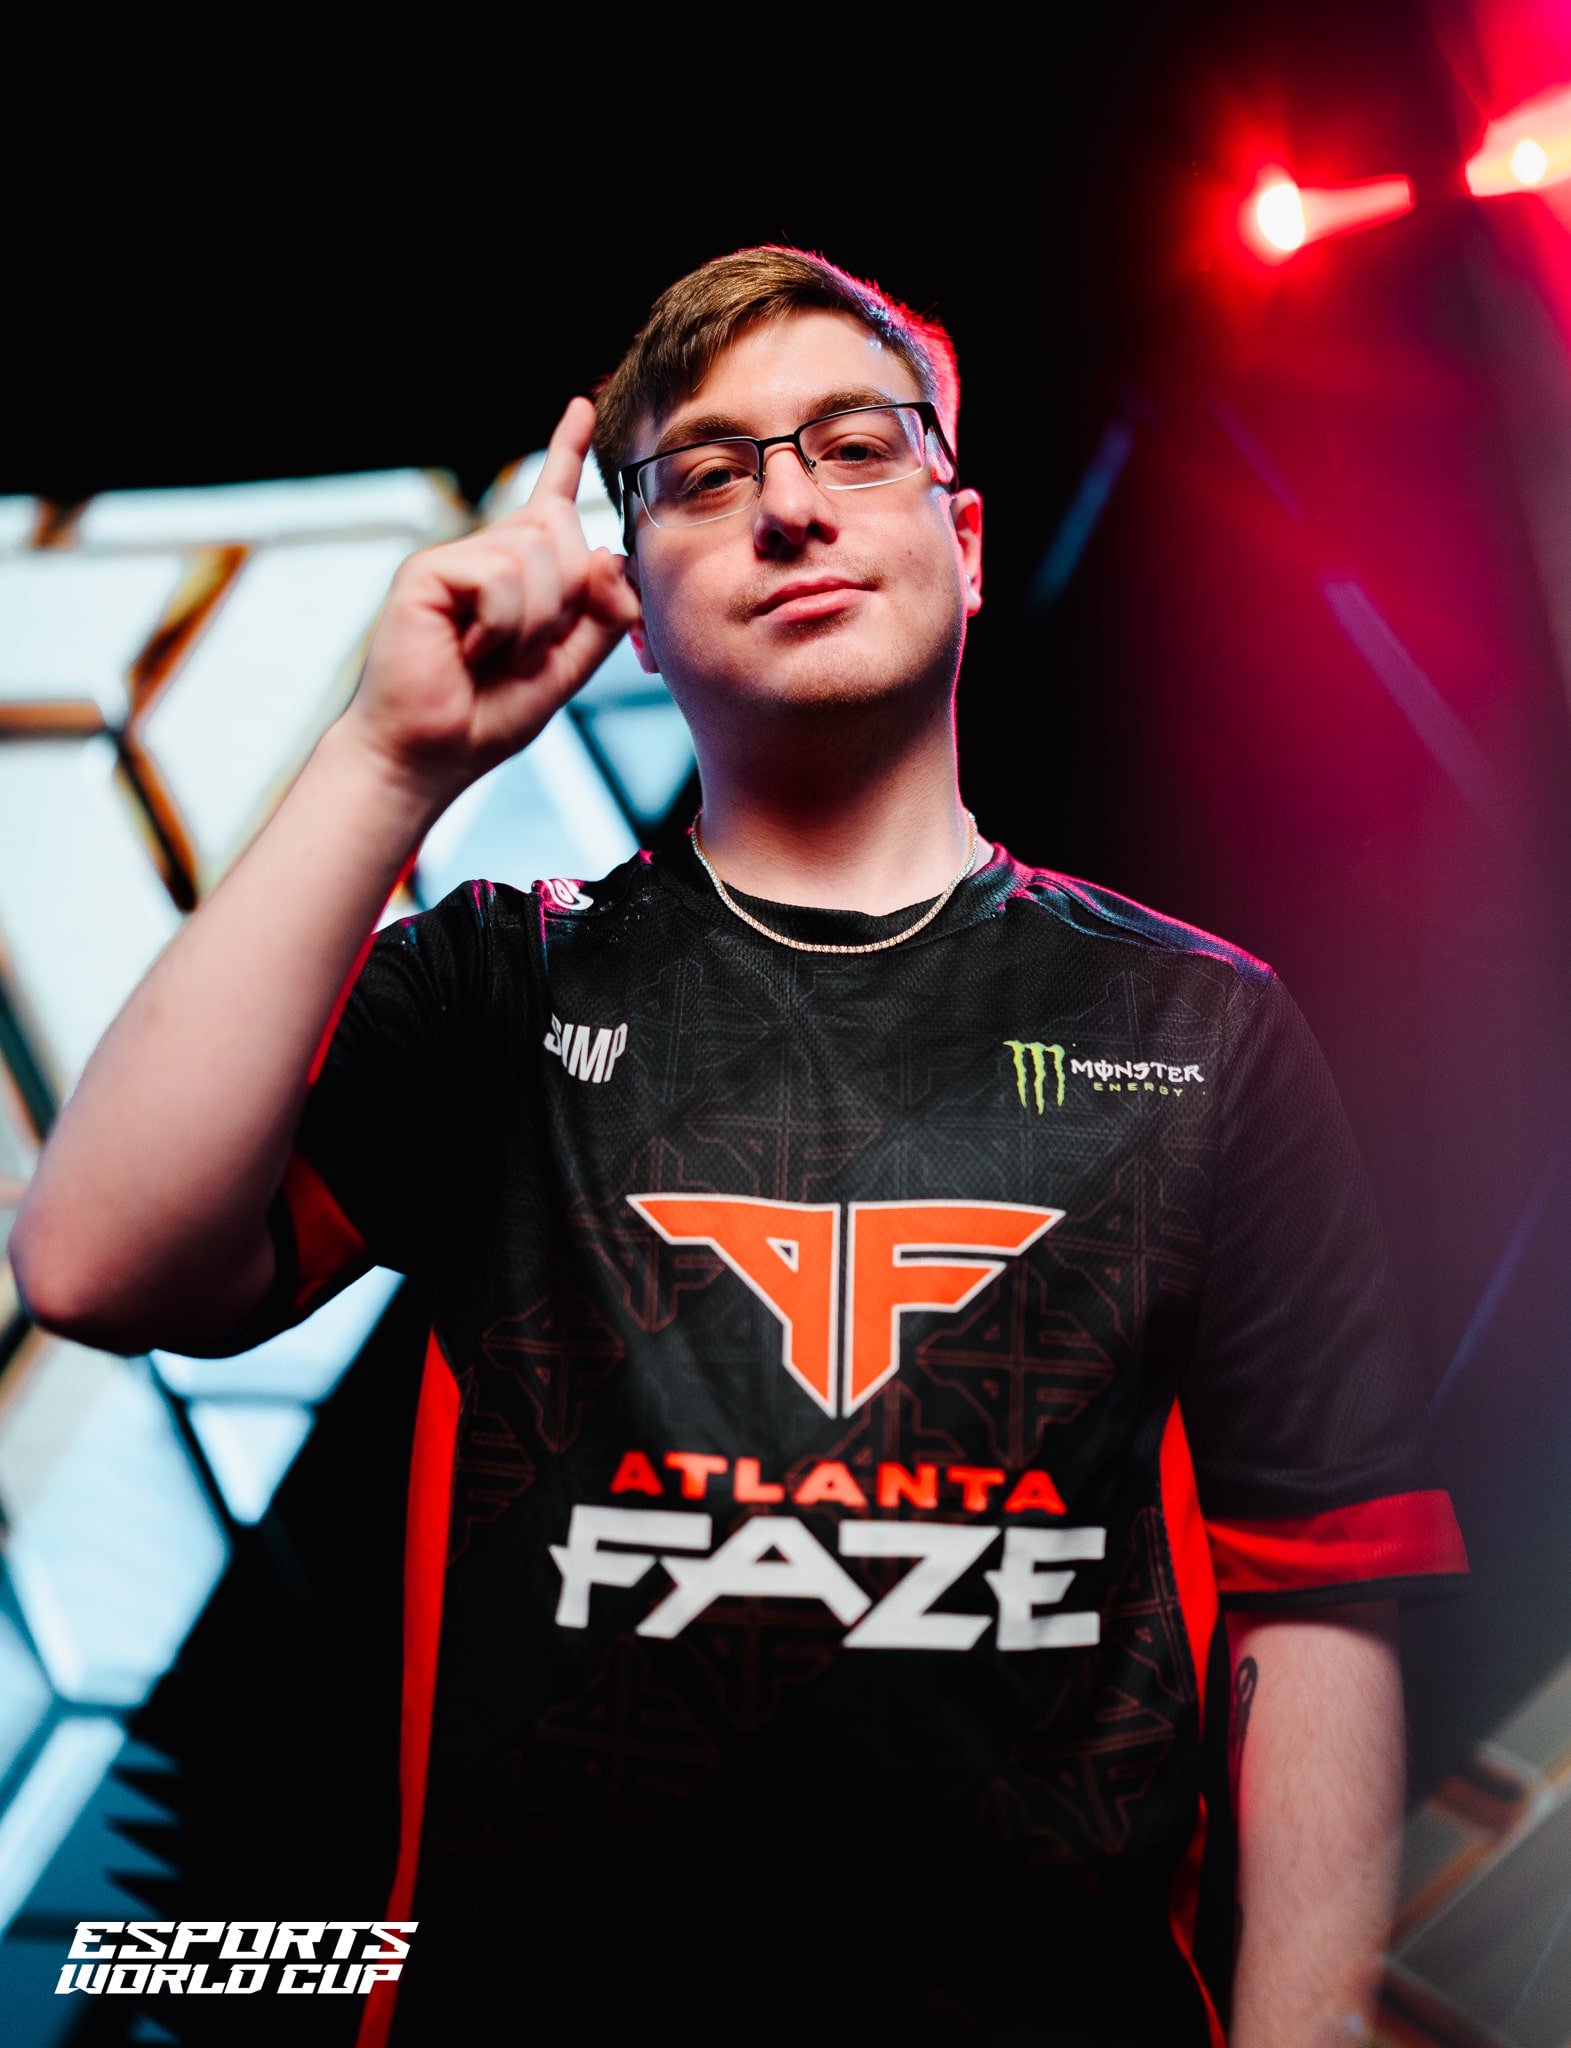
Illustrative only — all three cards use Simp’s real season stats, but only the left one uses his real rating (85.9, which clears the SUPERSTAR cutoff). The middle (80.0) and right (70.0) cards use hypothetical ratings so STAR and PRO have something to show here, and none of the three shows a rank, since there’s no real leaderboard position behind a hypothetical rating.
Attribution
Roster and event data derived in part from Liquipedia, used under CC BY-SA 3.0. EntryData is an independent analytics project and is not affiliated with, endorsed by, or sponsored by Activision, the Call of Duty League, or any CDL franchise.